Causal inference
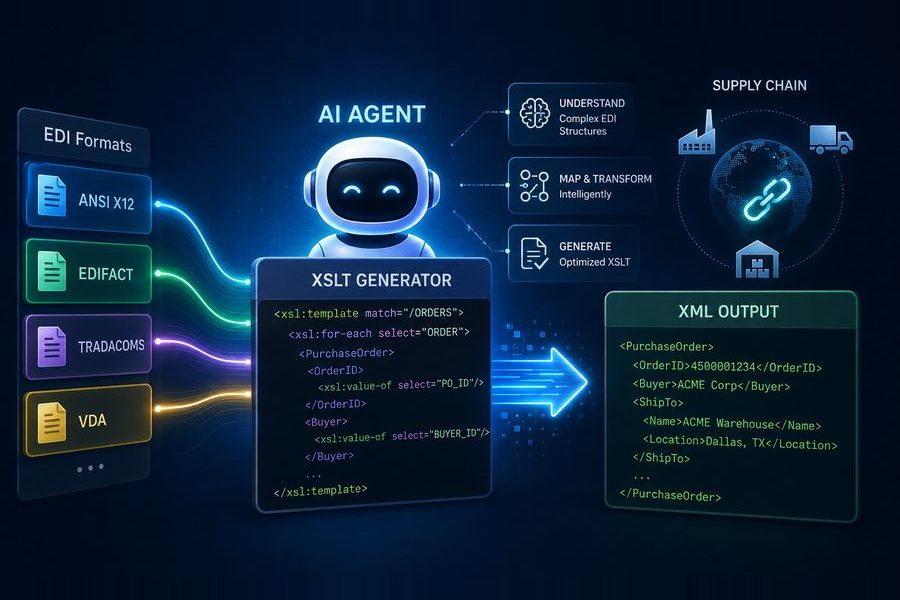
Building a single data mapping by hand took an estimated three to five weeks. I led a team of five through a nine-week proof of concept: a retrieval-grounded pipeline that drafts new mappings from 400+ existing ones, then a small in-house model set against GPT-4.1. I presented the trade-off to leadership as it was, 68% valid first try against 78%, in exchange for keeping partner data private, rather than claiming parity.
The mandate was open-ended: modernise how the business used its operational data, with no predefined scope. I drew the boundary myself, owning the pipeline and the KPIs built on it rather than claiming ownership of upstream systems I could not enforce. The decision I would defend hardest is that failing rows are set aside under a labelled reason code, never dropped, because a missing record is not a clean record.
Planning ran on spreadsheet moving averages fed by a single source, and an earlier attempt to patch it had stalled. My manager handed it to me because I questioned the assumption rather than the tool. I proposed a rebuild instead of a patch, proved it on one product line in a two-week parallel run, and only then asked for full commitment. Later I added a daily dashboard so supply surprises became same-day schedule decisions. When a stale input produced silently wrong forecasts, I flagged it the same day and put freshness checks in front of procurement. The teams that had been most sceptical trusted the system more afterwards.
A short, focused internship, and where I first learned that most of the loss in a process concentrates in a handful of exception modes, provided the data is clean enough to rank them honestly.
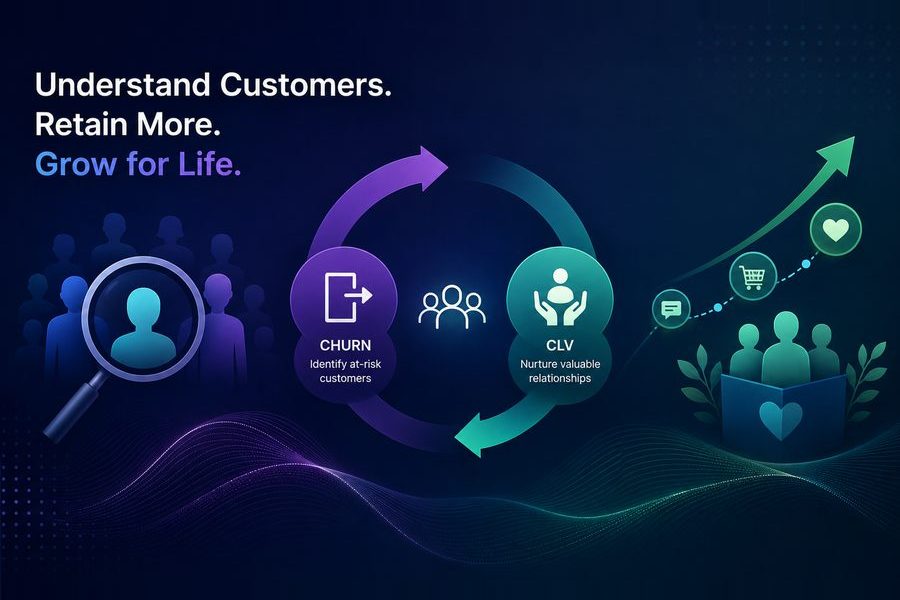
Save the customers worth saving.
Knowing who might leave isn’t enough; you need to know who is worth keeping. Features built from 410M log rows across 6.7M subscribers feed churn and lifetime-value models, and an expected-value layer merges both into one retention decision.
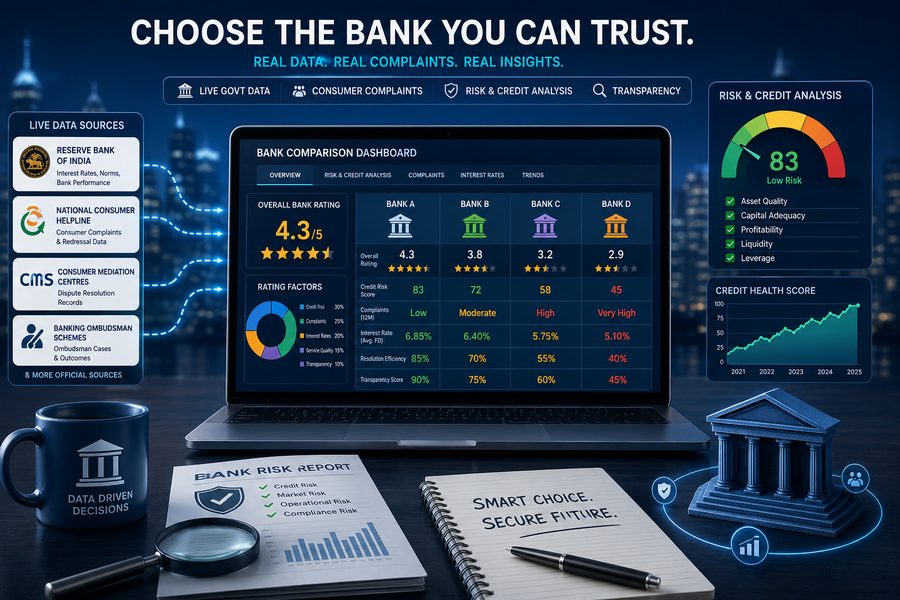
Bank rankings with no sales pitch.
Most comparison sites earn money from the accounts they recommend. BankCheck grades US banks and credit unions using only federal data, from FDIC and CFPB sources, so no affiliate incentive sits behind the ranking. It runs as a live Streamlit app.
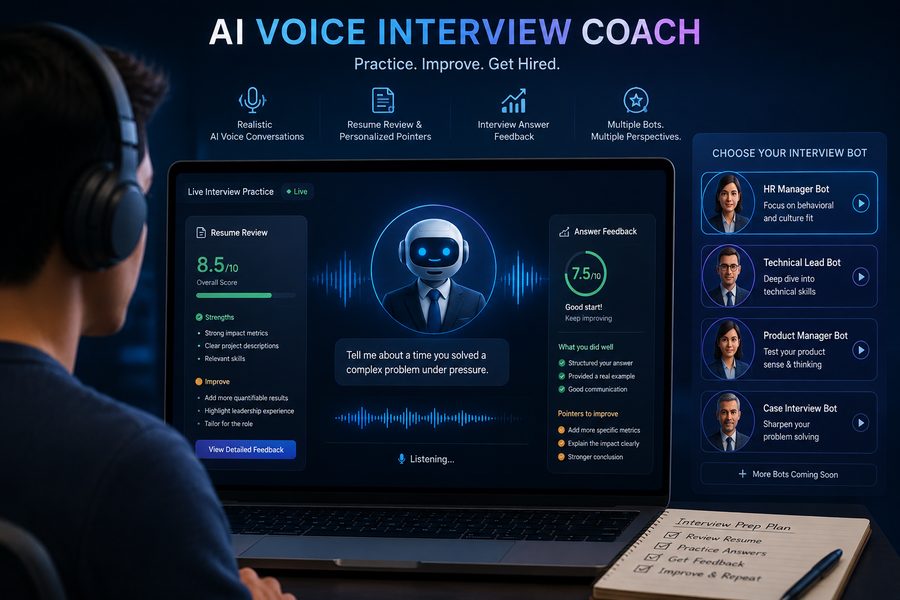
Practice interviews, minus the nerves.
A mock-interview and resume-review coach for any hour. Each phase of the conversation goes to whichever of three language models is strongest at it, trading cost against quality, so feedback stays sharp without a heavyweight model throughout.
Purdue University, Daniels School of Business · GPA 3.7
Graduate teaching assistant for AI for Business. Coursework across causal inference, machine learning, data management and analytics strategy.
Sardar Vallabhbhai National Institute of Technology, Surat · GPA 3.6
Where the habit of tracing a system back to its first principles started, and the reason I still reach for the underlying mechanism before the model.
AWS Academy Graduate · 2026
DataCamp · 2024
DataCamp · 2024
Amazon Web Services · CLF-C02
Microsoft · AI-900
Tableau
Purdue University · Summer 2026
Purdue University · Spring 2026
JCB India
JCB India
Indian Institute of Management, Ranchi
The case for routing by conversational phase instead of picking a single model, and what it costs you when you get the routing wrong.
Mar 2025A demand forecasting case study on why seasonal smoothing breaks against events that shift date every year, and what replaces it.
Graduated August 2026 and currently on OPT, authorised to work in the US now. Looking for opportunities in data science, analytics engineering and AI.
himanshuladdhad11@gmail.com